Latest
ChatGPT Codex Shared Limit: What Counts
Some posts on X, FourWeekMBA noted, called Instant chat unlimited. OpenAI's own sentence is narrower: “Instant chat will not draw from your usage.” That gap is the story of the ChatGPT Codex shared limit that OpenAI says begins in December for Plus, Pro and Business plans. Not counting is not the same as free, and the pool everything else draws on has no published size.
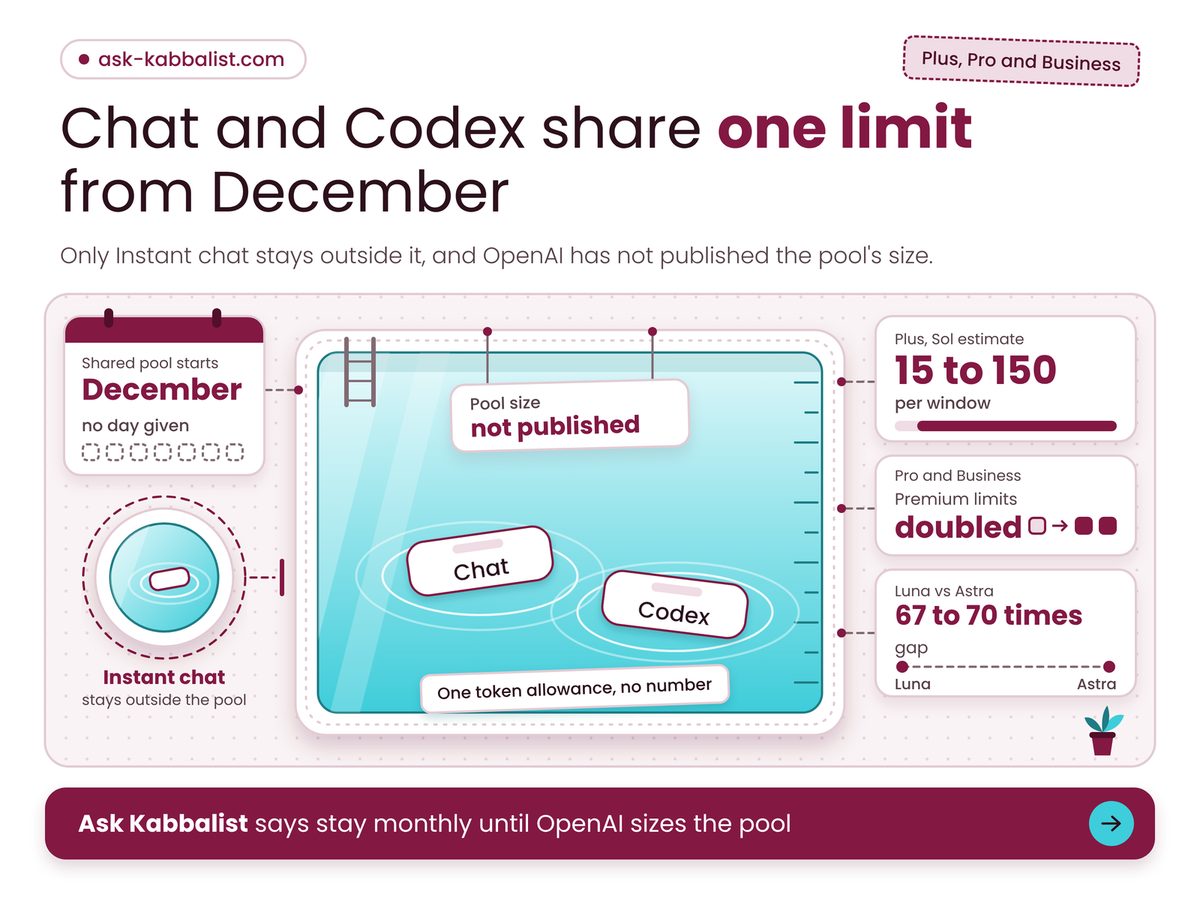
As reported from OpenAI's notice, from December chat and Codex on three named plans draw on one token allowance, and only Instant chat stays outside it.
- Instant chat does not draw on the allowance, but the quoted wording never calls it unlimited.
- Advanced models and complex tasks burn more tokens, so the same prompt costs different amounts.
- No pool size has been published, so no December message count exists yet.
- Free, Go, Enterprise and Edu are not named, so assume nothing.
Why does the ChatGPT Codex shared limit matter to a Plus subscriber?
It matters because chat and Codex stop being two budgets on one plan: from December, OpenAI says, they draw on a single token allowance, so a heavy coding day can leave less for advanced-model chat. As quoted by MIXED News on 2 November 2026, OpenAI's help article says usage will be measured in tokens, the units a model processes and generates, and that more advanced models and complex requests generally consume more. FourWeekMBA, quoting the same page on 31 October 2026, lists today's Plus estimates for Work and Codex per five-hour window: GPT-6 Astra 5 to 45 local messages, GPT-6 Sol 15 to 150, GPT-6 Luna 350 to 3,000. OpenAI calls them estimates, and they predate the pool.
So the useful question is not how many messages Plus includes, because no single number exists. It is which model you spend them on. A Plus subscriber on the OpenAI Community forum wrote in August 2026 that they keep Sol models for planning and architecture work, which is the habit a token budget rewards. Plans keep their names while contents move: ChatGPT Free's unlimited text chats arrived tied to one small model, and Google AI Plus drops Gemini Pro on 13 November.
Four numbers decide what reaches you: a wait, a carve-out, who is covered and how fast allowances move. BleepingComputer reported on 29 October 2026 that OpenAI dropped a planned cut to Pro 200 and doubled limits across Pro 100, 200 and 500 and Business Premium, so a quoted limit can be stale within weeks.
Wait To The Earliest Start
22 days
Derived: today to 1 December
Instant Chat's Draw On The Pool
0 tokens
Carved out, per the notice
Plans Named In The Notice
3 plans
Free, Go, Enterprise, Edu unnamed
Pro And Business Premium Limits
2x
Raised after a planned cut
The carve-out is defined by what it does to a counter, not by how much you may chat. The quoted wording says nothing about other limits on Instant itself, or rather, nothing in the reports we read does.
Not drawing from your usage is not the same as unlimited, and until OpenAI numbers the pool, nobody can say how many December messages a Plus plan includes.
What counts toward the pool, plan by plan?
Only Plus, Pro and Business are named, and for them chat and Codex share one token allowance from December, while Instant chat is the single named exemption and every other plan is left unstated. Read the table by plan first, then hold the row against what you actually run.
| Plan | What OpenAI says | What it means for you |
|---|---|---|
| 📊 Plus | Pool from December; 5-hour estimates until then | Only Instant chat sits outside it |
| 💰 Pro | Pro 100, 200, 500: no five-hour limit today | You spend a budget, not a window |
| 🧾 Business | Pool from December; no day or size given | Ask your admin before budgeting seats |
| 🌍 Other plans | Free, Go, Enterprise, Edu: not named | Assume no change until OpenAI says |
The Pro row is the odd one out: a Pro seat spends an allowance with no five-hour clock, while Plus has lived inside windows. Our call: if OpenAI keeps windows for Plus, the model gap below will matter more.
Sort what you do into the two shaded workloads that spend the pool and the one that does not. The 67 to 70 times gap is derived: Luna's 350 to 3,000 messages against Astra's 5 to 45, at the ends of each range.
Worked example: take a Plus subscriber on GPT-6 Sol who sends 20 requests on a working day, half of them as Instant chat. Assumptions: the quoted Sol estimate of 15 to 150 messages per five-hour window holds, Instant chat counts as zero, and the unnumbered December pool behaves like today's window. Counted requests are 20 × (1 - 0.5) = 10. At the heavy end, 10 ÷ 15 = 0.67 of one window. At the light end, 10 ÷ 150 = 0.07. This is our arithmetic, not an OpenAI figure; redo it with your own request count below.
Where does the shared pool stay vague?
It stays vague on size, start date and conversion: the quoted wording gives no December allowance for any plan, no day of the month, and no rule for turning tokens into messages.
Reader reports show why the missing conversion matters. A Pro subscriber on the OpenAI Community forum wrote in August 2026 that their 200 plan was “lasting few hours”, and a $100-plan subscriber wrote, “I can barely work for one or two hours before my entire limit is exhausted.” Those posts predate the pool and the October doubling, and are anecdotes, not measurements.
Our view: a token budget with no stated size is a price you cannot read. Microsoft 365 Family is sold for six people, but Copilot in the apps works for one, and Google's free Gemini tier now runs on Flash-Lite after losing Flash and Pro on 9 October 2026. The label stayed; the contents moved.
- Reports say Settings will show remaining usage and reset times; OpenAI expects most people to wait no more often than now, an expectation, not a guarantee.
- Reports say that at a limit you can wait, upgrade, or buy credits for eligible features, with no dollar rate stated.
Key Takeaways to act on
- You run Codex on the largest model most days: expect faster drain.
- Nearly all your use is quick chat: confirm it runs as Instant, not an advanced model.
- You are on a plan the notice does not name: ask support or your admin.
The decision is whether your tier still fits once chat and Codex share a pool, and until OpenAI publishes its size, stay on monthly billing and keep your current plan. This week, open ChatGPT Settings, note which model you spend most on, and rerun the calculator above with your own request count. That is wrong for you if nearly all your use is Instant chat; check OpenAI's own usage limits page first, which outranks every report here. Weighing a long-term plan elsewhere? Read our check of the claim that only Anthropic sells one for Claude Pro.
How we checked this
We read reports that quote OpenAI's help article on ChatGPT and Codex usage limits, which we could not open directly: FourWeekMBA (31 October 2026, updated 5 November), MIXED News (2 November 2026) and BleepingComputer (29 October 2026). The worked example assumes the quoted Sol estimate and that Instant chat counts as zero. No product was tested hands-on for this article, and the December pool size is still unpublished. Last verified: 9 November 2026. Edited by Sheftali, reviewed after publication. Spotted something out of date? Tell us and we will correct it.